Troubleshoot Crawl Scope in LLMIC
Find where an expected URL stopped producing usable evidence.
You expected a section of the website to appear in a crawl, but its URLs are missing. Increasing every limit is tempting. It is also a poor first test: the next run may be larger while leaving the original cause unexplained.
Troubleshoot crawl scope in LLMIC by following one missing URL from input to observation. Establish whether the crawler received it, could discover it, was allowed to request it, and obtained the expected content. Once you identify that failure point, change one relevant setting or site condition and repeat the narrow test.
Preserve the Run Before Changing Anything
Save the current crawl and write down its mode, starting URL, limits and finish state. Keep the expected URL list if one exists. A new run with different settings cannot explain the old result unless you retain the old configuration and evidence.
Choose one representative missing URL. Prefer a URL whose expected behavior is clear, such as a public documentation page linked from a known hub. Avoid beginning with an ambiguous redirected or authenticated address if a simpler example shows the same problem.
Record the symptom precisely. “The URL is absent” differs from “the URL has a request failure,” which differs from “the URL returned a login page.” Those observations point to discovery, access and content problems respectively. A single label such as “not crawled” obscures that distinction.
Check Whether the URL Entered the Investigation
In URL List mode, inspect the supplied list. Confirm the exact URL is present and was entered as an absolute URL. Check for copied punctuation, incomplete schemes, extra cells or an unexpected hostname. Retain the original list while preparing a corrected copy.
In Sitemap mode, inspect the actual sitemap used for the run. A URL listed in a different sitemap or a CMS screen may not have been part of this input. Confirm the precise address rather than assuming every sitemap on the domain contains the same inventory.
In Auto-Crawl, follow the navigation route from the starting page to the missing page. Check whether each step exposes a link the crawl can discover under its rendering configuration. A browser interaction that requires a form submission is not automatically equivalent to an ordinary linked path.
Use a Direct-URL Check to Separate Causes
Place the representative missing URL in a small URL List and run a focused check. Keep the relevant access and rendering settings consistent with the original run. This test changes the discovery input; it should not simultaneously change every other condition.
If the direct check produces usable page evidence, investigate the original link path, depth or input inventory. If it fails too, inspect the request outcome and page behavior before blaming discovery. If it returns different content than you expected, examine redirects, authentication and rendering.
This is a diagnostic comparison, not proof that the broader crawl is now repaired. A successful direct request establishes access to that URL in that test. You still need to repeat the original discovery route after fixing the underlying cause.
Match the Next Action to the Observation
| Observation | Next diagnostic step | Avoid this shortcut |
|---|---|---|
| URL never appears in the supplied list | Correct the input and retain both versions | Raising depth for a list-entry problem |
| Direct URL works but linked crawl misses it | Inspect the source link and traversal boundary | Calling the page broken |
| Request is denied or challenged | Check the site’s access rules with its owner | Repeatedly increasing request speed |
| Redirect does not reach the intended page | Inspect the destination sequence and limit | Treating the first redirect as a successful page fetch |
| Response contains little expected content | Compare the visible page and rendering configuration | Assuming an empty observation means empty published content |
| Run stops at its configured ceiling | Determine which intended URLs remain unresolved | Calling the ceiling the site’s actual size |
For access denials, coordinate with the website owner. A normal browser session can have cookies or permissions the crawler does not possess. Do not assume changing a user-agent label grants access, and do not use troubleshooting as a reason to bypass site restrictions.
Inspect Limits Only After You Have a Hypothesis
Use More, then Settings, and review Crawling. Compare the Spider Limits with the intended navigation path and inventory. If a depth boundary explains the missing page, change that boundary for the diagnostic run and keep the other settings stable.
If Max Pages was reached, first look for an unexpectedly expanding URL set. Repeated filter or tracking variations can make the investigation larger than intended. Increasing the ceiling may be appropriate, but it should follow an inventory decision rather than hide an uncontrolled input set.
If redirect handling is the suspected cause, inspect a small sample of affected URLs. Determine whether the chain is intentional and finite. A configuration change that allows more hops is not a substitute for fixing a loop or an incorrect destination on the website.
Worked Example: A Guide Missing From a Linked Crawl
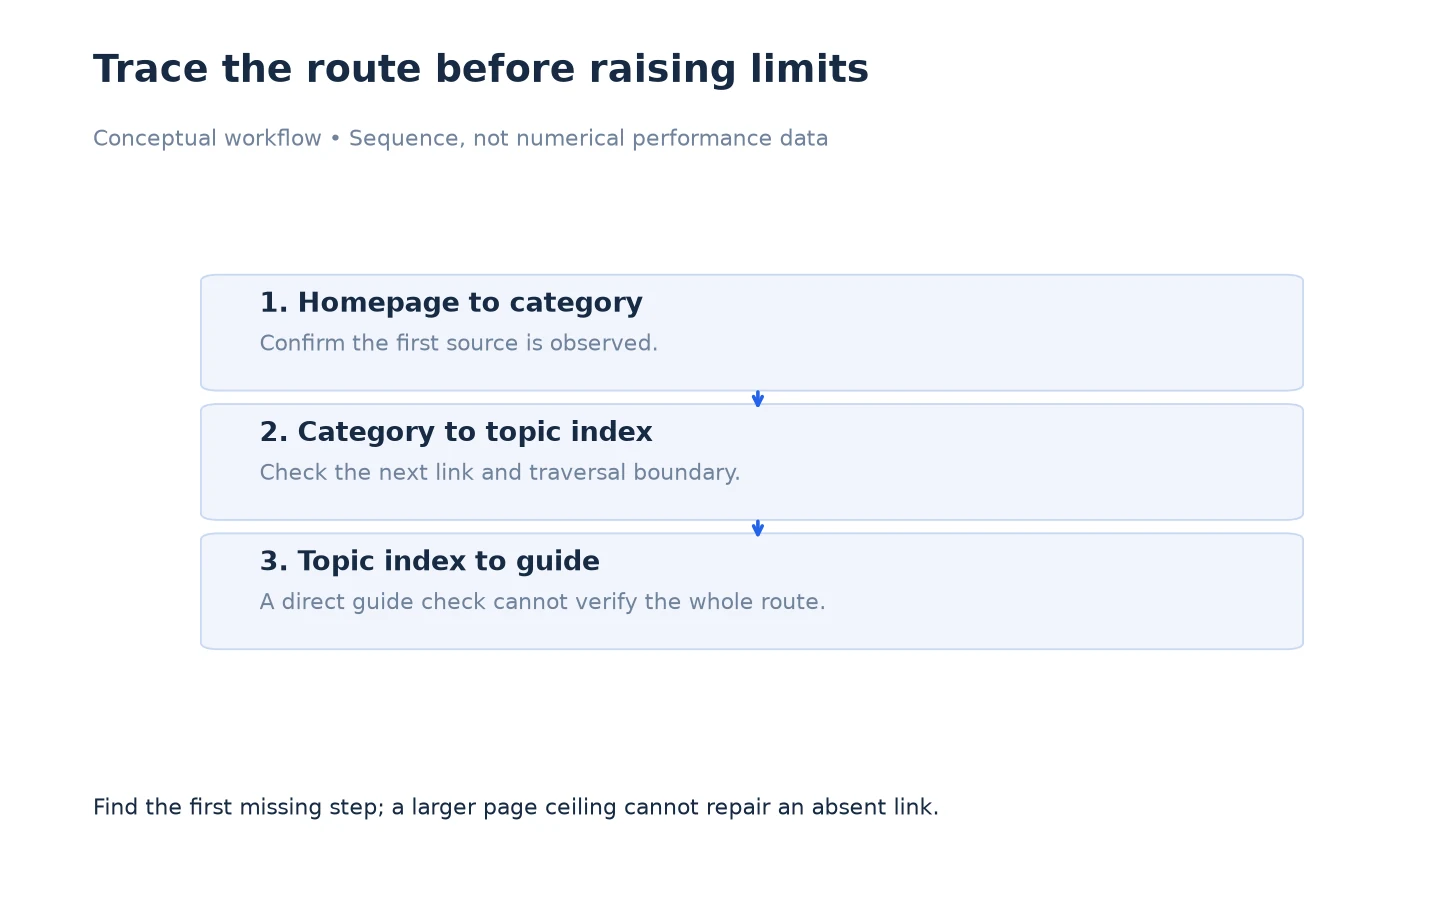
This is an illustrative scenario. A team starts at its help homepage with a shallow traversal limit. A particular guide is absent. The team first confirms that the guide loads as expected in a direct URL List check using the same rendering and access settings.
Next, it traces the site’s navigation. The homepage links to a category, the category links to a topic index, and the topic index links to the guide. The original traversal boundary does not cover the full route. The team increases only the relevant depth setting for a small diagnostic rerun and confirms that the guide now appears.
The conclusion is limited but useful: the original omission was consistent with the selected traversal boundary. The team has not established that every guide on the domain is discoverable, nor that Google has indexed this one. It updates the scope note and chooses a representative set of other deep pages for the broader verification.
Close the Investigation With a Reproducible Finding
Write the starting symptom, the evidence inspected, the one change made and the retest result. If the cause remains uncertain, preserve that uncertainty. “Direct URL succeeds; linked discovery remains unresolved” is a useful engineering handoff. “Crawler fixed” without a repeated test is not.
Include one affected URL and its source page where appropriate, but remove credentials and private tokens. When the original route works again, use Verify Changes to Crawl Scope in LLMIC to check that the repair did not create an unintended expansion elsewhere.
Questions About Missing Crawl Results
Why does a URL work in my browser but fail in LLMIC?
The two requests may differ in cookies, authentication, rendering or access treatment. Compare the actual result instead of assuming the browser’s successful session proves anonymous crawler access.
Should I disable robots restrictions to recover missing pages?
Do not make that the default repair. First establish whether a restriction explains the omission and whether the investigation is authorized. Preserve blocked URLs as coverage limitations when they cannot appropriately be inspected.
Can a page be reachable directly but absent from Auto-Crawl?
Yes. Direct input and linked discovery use different starting evidence. Inspect the internal route, the relevant depth and whether the links are available under the chosen rendering configuration.
What if increasing Max Pages produces even more unexpected URLs?
Pause the expansion and inspect the URL patterns. Decide which variations belong in the investigation. Keep the original run so that a larger result set does not obscure the cause of the initial ceiling.
Does a 200 response rule out an access problem?
No. Inspect the returned content when the outcome is suspicious. A challenge or login screen can differ from the intended page even when the response appears successful.
How many settings should I change in one diagnostic test?
Prefer one setting tied to a stated hypothesis. If several conditions must change, record each and explain why the result cannot isolate a single cause. A controlled test is easier to interpret.
When should I rerun the original crawl?
After the narrow test supports a fix. Repeat the original input route with the intended final settings, then reconcile the previously missing URLs and inspect for new exclusions or scope expansion.
Sources, Statistics and Measurement Notes
The Settings entry and Spider Limits were inspected in the installed LLMIC app on 5 October 2026. The help-center scenario is an illustration, not a measured customer investigation. No recovery rate or performance improvement is claimed.
Google’s introduction to robots.txt, accessed 5 October 2026, provides background on crawl restrictions. Its description of Google’s handling should not be treated as proof that every crawler handles each edge case identically.