Configure Canonical Signals in LLMIC
Collect both sides of the canonical relationship.
A canonical review begins with a relationship: this URL declares that another URL represents its content. To investigate that relationship, you need the source page, the declared target and enough context to understand why the site prefers that target. Collecting only the source can leave the most important part of the finding outside your evidence.
This guide prepares an LLMIC audit for canonical investigation. It does not configure canonical tags on your website. You will define a small set of page variants, preserve their identities and make sure the intended target is included in the review before interpreting missing-target or canonicalised findings.
Define the Preferred URL With the Site Owner
Start with one real content group, such as a public guide and a parameterized version of that guide. Ask which URL the website intends to present as the preferred version and why. Write that decision down independently of the current markup. Otherwise, the existing declaration may become the assumed answer even when it is the defect under investigation.
Include a distinct neighboring page as a control. Its content should remain separate from the group being reviewed. This control is useful when a shared template accidentally points many unrelated pages to the same target. A review that contains only similar variants may miss that broader mapping error.
Do not choose a target merely because it has the shortest address or the highest local score. The task is to inspect a deliberate content relationship. An operator’s preferred URL, the site’s declared canonical and a search engine’s selected canonical are separate records. Keep their sources clear from the beginning.
Build a Source-and-Target Input List
Record each source URL exactly as it appeared in the report or page request, including meaningful query parameters. Add the declared target and the owner’s intended target if they differ. This creates a bounded test set that can explain both the current behavior and the proposed correction.
Check crawl scope before starting. A target on another host or outside the selected path may not be part of the collected dataset. That does not prove the target is unavailable. It means you must arrange a separate authorized observation or leave the target’s status unknown. Do not expand the crawl broadly without a reason tied to the investigation.
Review URL handling when parameter variants matter. If a collection process normalizes two inputs into one identity, retain the original request list in your notes and reconcile it with the resulting rows. The important question is whether the evidence still distinguishes the variants that motivated the test, not whether the final table looks tidy.
| Input | Why it belongs in the test | Identity to preserve |
|---|---|---|
| Affected source page | Contains the observed declaration | Original requested URL and collected page URL |
| Declared target | Tests the actual current relationship | Resolved target URL and collection state |
| Intended target | Defines the proposed correct relationship | Owner-approved preferred URL |
| Distinct control page | Detects an overbroad shared-template change | Its own intended canonical relationship |
Use the crawl scope guide if the collected population does not match the input list. Fix the evidence boundary before interpreting a target-absent warning as a website defect.
Preserve the Page Evidence Needed by the Detector
LLMIC’s reviewed canonical detector operates on auditable HTML page records. It reads the extracted canonical value, available HTML and the target records in the crawl context. Keep the saved crawl rather than retaining only the issue total, because later review may depend on the raw declaration or the target’s collected state.
The detector can surface missing, multiple, conflicting, relative and fragment-containing declarations, as well as relationships to another URL. These are investigation categories, not instructions to apply the same repair to every page. For example, a deliberate duplicate can point elsewhere, while an independent article should not inherit an unrelated template target.
If a finding concerns more than one declaration, preserve the source markup that contains them. A single extracted canonical field cannot represent every competing tag. Likewise, an HTTP-header question needs the actual relevant response-header evidence; do not assume that the Pages CSV’s Canonical Link Element 1 field is a complete record of every canonical signal.
Keep Observation Settings Stable
Record the collection time, selected agent, relevant rendering mode and access conditions. If a page’s canonical appears to change between source and rendered content, you need those settings to explain what was inspected. Avoid presenting two different collection modes as a simple before-and-after site change without identifying the difference.
Do not change several collection settings to make a warning disappear. First determine whether the missing evidence concerns retrieval, rendering, extraction or scope. A smaller reproducible collection is more useful than a large rerun whose inputs cannot be compared with the baseline.
Save the baseline before asking the website owner to modify a template or SEO setting. LLMIC’s local audit configuration is not the publishing system for those changes. The handoff should name the source page, intended relationship and observed declaration so the owner can change the correct system.
Worked Example: Two Variants and One Independent Page
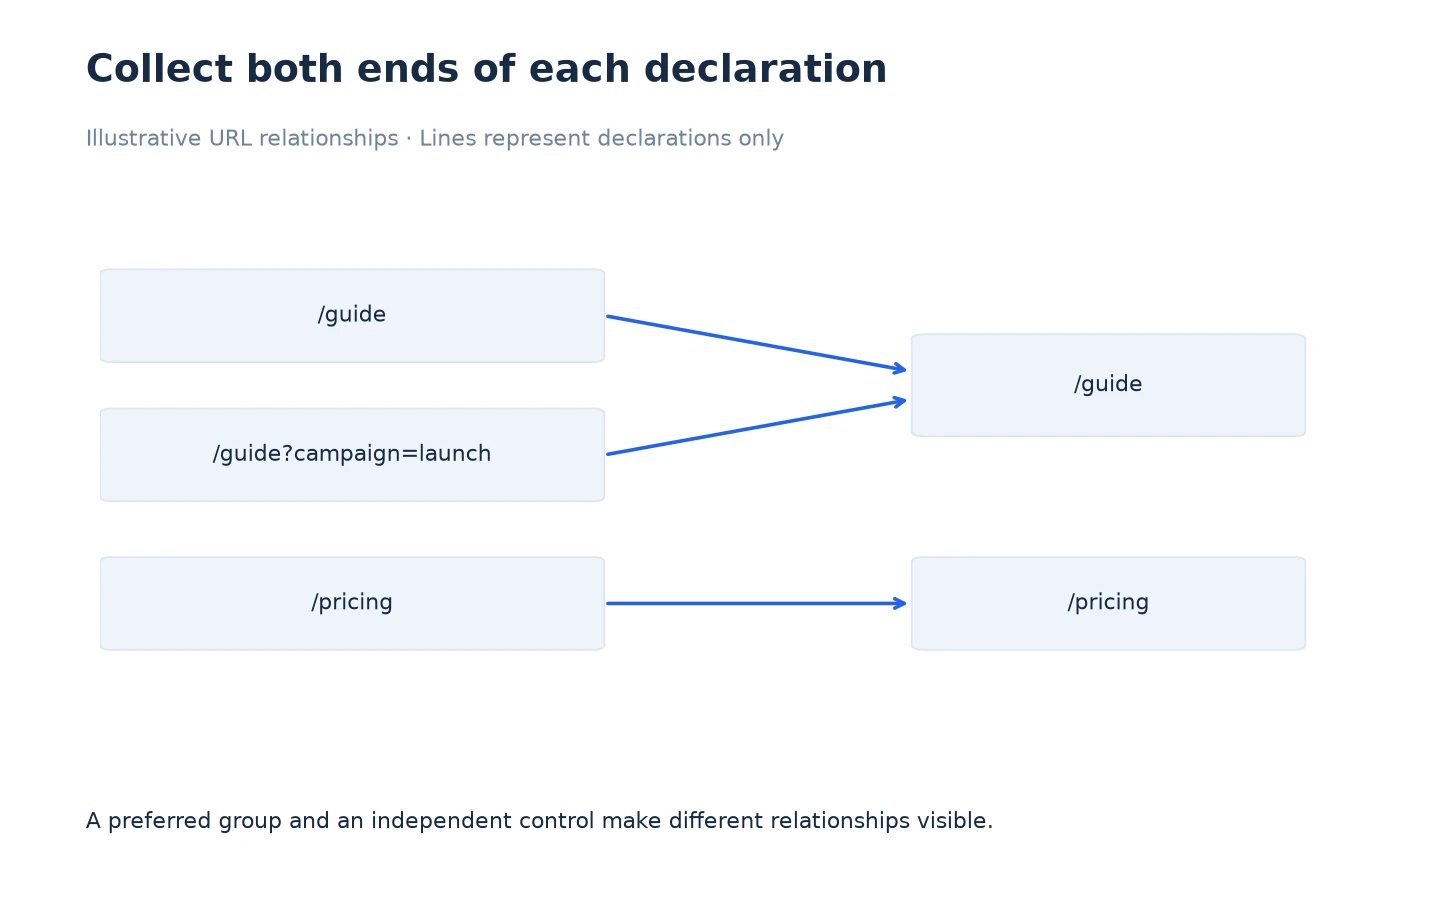
Consider an illustrative group containing /guide and /guide?campaign=launch. The owner intends both to identify /guide as the preferred version. A third input, /pricing, is an independent page and should retain its own relationship. These three inputs form a small, understandable configuration test.
The relationship diagram shows two source nodes converging on the guide target, while the pricing node stays separate. The connecting lines describe declared relationships, not link authority, traffic flow or a measured search-engine decision. No line thickness implies that one signal has a quantified strength.
Before collecting, add /guide as a target even if it already appears as a source. After the run, reconcile the input list with saved rows and inspect the target’s observation. If the parameterized variant was collapsed during URL handling, record that limitation and obtain the evidence needed for the original variant rather than assuming it was separately tested.
This example catches two common evidence gaps: a target omitted from the crawl and an unrelated page accidentally included in the same canonical group. The configuration succeeds when both relationships can be inspected, not when every source becomes self-referential.
Complete the Setup With a Review Worksheet
Create columns for source URL, declared target, intended target, target observation, collection time and unresolved limitation. Keep those fields separate from the later decision. The worksheet makes it possible to ask whether a relationship is intentional before deciding whether its markup or target requires a change.
Continue with reviewing canonical results after collection. When a change is needed, retain this same input set for fresh verification. A reusable source-and-target worksheet is the output of configuration; a guarantee about search selection is not.
Frequently Asked Questions
Does configuring this audit edit canonical tags on my site?
No. This workflow prepares local collection and interpretation. The site owner must change the system that emits the website’s markup or response headers.
Why include the target in the input list?
A source declaration identifies a destination but does not establish its current response or content. Collecting the target provides evidence for that second part of the relationship.
Is a canonical pointing elsewhere always a problem?
No. It can be intentional for a duplicate or similar variant. Compare the relationship with the owner’s content policy before assigning a repair.
Should I remove query parameters before the audit?
Preserve parameters that define the case being investigated. Reconcile original inputs with collected identities so URL handling does not silently erase a relevant variant.
Can a missing target row prove the target is broken?
No. It may be outside scope or absent from the saved dataset. Obtain target evidence or mark its state unknown rather than converting a coverage gap into a response claim.
What proves which canonical Google selected?
That requires separately sourced search-engine evidence. A local declaration or LLMIC finding describes website signals and cannot by itself establish Google’s selected URL.
What should remain unchanged between verification runs?
Keep the source-and-target inputs and relevant collection settings comparable. Document any necessary change so differences in collection are not mistaken for differences on the website.
Sources, Statistics and Measurement Notes
The product boundaries were checked in CanonicalIssueDetector and PagesExportService on 5 October 2026. The three-URL relationship diagram is an original illustrative scenario, not customer data or a model of signal strength.
Google’s canonicalization documentation distinguishes declared preferences from Google’s selection and discusses several canonicalization methods. This guide focuses on preparing the local evidence needed to review such relationships.