How to Audit Website Redirects
Audit website redirects from the original link to the final page. Identify chains, loops and wrong destinations, then create a clear repair plan.
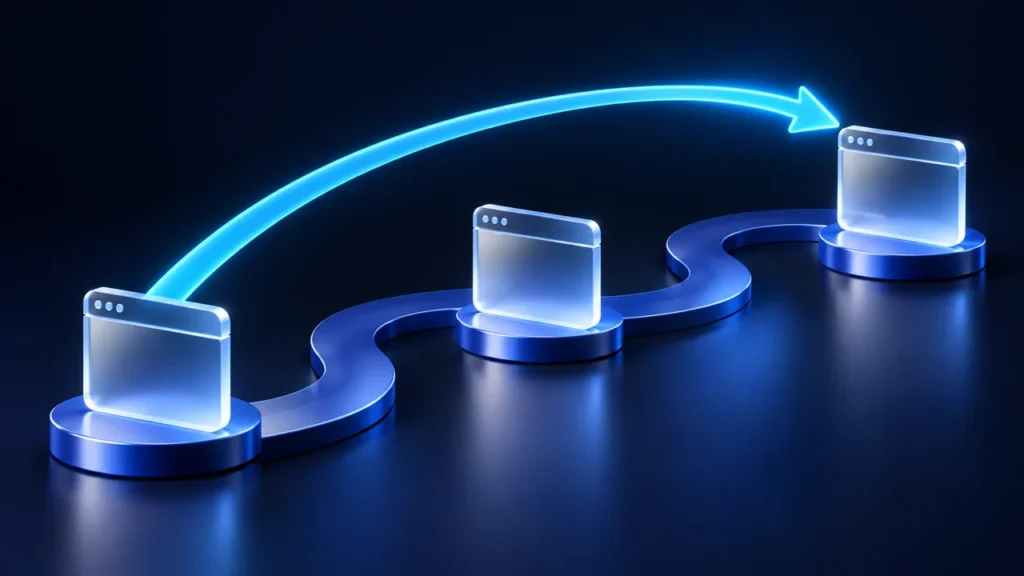
A customer clicks an old link to a running shoe. The browser visits the old domain, moves to HTTPS, changes the product path and finally opens the new shoe page. The customer may notice only a delay. The audit should reveal the entire journey.
A redirect audit follows an address until it reaches a destination or fails. Its purpose is not to eliminate every redirect. It is to make necessary moves direct, meaningful and consistent, while finding journeys that end at the wrong place.
The Workflow at a Glance
- Collect actual entry URLs
- Trace every redirect hop
- Review final page meaning
- Repair the responsible rule and retest
| Observed Journey | Meaning | Next Action |
|---|---|---|
| Old URL → correct page | Necessary move works | Retain and update current links |
| Old → intermediate → correct | Potential unnecessary chain | Review rule ownership |
| Old → unrelated page | Intent lost despite success status | Approve a better mapping |
| A → B → A | Loop | Correct conflicting rules |
Start With Real Entry Points
Collect old URLs from the migration map, internal links, sitemaps and relevant Search Console records. Keep the source of each address. A URL found in a current menu deserves a different discussion from an obsolete address retained only for historical visitors.
Do not begin by generating endless combinations of paths and parameters. Define the hosts and patterns you own, then work from observed or planned URLs. This keeps the audit manageable and prevents an invented test set from overwhelming the actual customer journeys.
Record Every Hop
For each entry, save the requested URL, response status, destination header and next response until the journey ends. Keep the order intact. A report showing only “final status 200” can conceal a loop that was bypassed by a tool, an unnecessary intermediate address or an irrelevant final page.
Separate server redirects from browser-driven navigation. A JavaScript navigation may require rendering and might not appear in a simple HTTP trace. State which layers were measured and keep an unobserved layer marked unknown. Do not label a route clean merely because the chosen tool did not execute it.
Check Destination Meaning
The final page should satisfy the intent of the old address when a relevant replacement exists. Compare the old page’s purpose with the destination’s actual content. A product redirecting to a generic homepage is not a good experience just because the response succeeds.
Ask the product or content owner to approve uncertain mappings. A newer model may be a suitable successor, or it may be materially different. The auditor can expose the journey, but should not silently make merchandising decisions based on a similar-looking slug.
Distinguish Moves From Temporary Detours
Permanent moves and temporary routing serve different intentions. Record the business reason before choosing a response type. A short maintenance detour should not be treated as an irreversible content migration, while a retired article needs a deliberate long-term destination or removal policy.
For ordinary page moves, server-side redirects are generally the clearest implementation when available. Application requests and form submissions need extra engineering care because redirect semantics can affect request methods. Keep those flows outside a casual bulk SEO rule and test them with the application owner.
Find the Rule Behind the Pattern
Ten thousand URLs can share one extra host-normalization hop. Group the pattern, but preserve examples and the complete affected list. Identify whether the CDN, web server, application or SEO plugin creates each step. Competing layers often explain chains that no single configuration screen reveals.
A direct mapping from the old address to the intended final page may remove unnecessary hops, provided it preserves the required behavior. Test the rule on a normal path, an encoded path, a query-bearing URL and a deliberate exception before broad deployment.
An Illustrative Shoe-Store Audit
Suppose 200 observed legacy URLs are tested. One hundred and forty reach the correct page directly, 35 take an unnecessary intermediate hop, 15 land on an unrelated category, five loop, and five cannot be measured because of network failures.
The team has 140 verified direct mappings, 55 measured journeys requiring review and five unknowns. The 35 chains may come from one host rule, while the 15 bad destinations require individual business decisions. Those are different tasks even though both appear under redirects.
Repair Discovery as Well as Routing
Once a permanent destination is approved, update current internal links to use it directly. A redirect can support old bookmarks and external links without remaining the preferred route inside your own navigation. Inspect a real source page after the edit; a mapping spreadsheet cannot prove the link changed.
Review sitemap entries and canonical annotations for consistency with the new destination. Keep necessary legacy redirects available for visitors still using old links. Cleaning current discovery does not mean deleting the compatibility path immediately after the audit.
Write the Handoff Around Journeys
For each task, attach the original URL, observed hops, intended destination and owning component. Define success in terms of the exact journey, including the final content. Avoid a ticket that says only “reduce redirect count,” because a shorter path to the wrong page is still wrong.
After release, retest the original entries rather than crawling only the new site. Include the query and host variants covered by the rule. Save failures and unavailable results separately so a partial deployment cannot disappear inside a favorable average.
Frequently Asked Questions
What is a redirect chain?
It is a sequence in which one redirect leads to another before the final page. Some normalization steps may be intentional. Record the full journey, then decide whether the original address can safely reach the intended destination more directly.
Is every redirect bad for SEO?
No. Redirects are useful when content moves or URL variants need consolidation. Review unnecessary hops, loops and irrelevant destinations rather than trying to remove every redirect. The goal is a dependable journey that preserves the user’s intent.
How do I find a redirect loop?
Trace the ordered destinations and detect a repeated address. Retain the involved rules and hosts for the developer. A browser error alone may show the symptom without identifying which layers send requests back to each other.
Should old product pages redirect to the homepage?
Not automatically. Choose a genuinely useful successor when one exists. If there is no suitable replacement, use an appropriate retirement experience rather than disguising removal with an unrelated successful page.
Should internal links still point through redirects?
For permanent moves, update current links to the preferred destination where practical. Keep the redirect for older external links and bookmarks. Test the edited source page as well as the old URL so both paths are verified.
Can I audit redirects without rendering JavaScript?
You can inspect server response chains, but may miss browser-driven navigation. State that scope clearly. Render selected cases when the observed journey depends on client execution, and keep those findings distinct from HTTP redirects.
Will fixing chains increase rankings?
The work can simplify delivery and remove broken journeys, but it does not guarantee rankings. Verify the technical route first and assess later traffic separately, with other site changes and demand conditions kept visible.
Sources, Statistics and Measurement Notes
- Redirects and Google Search — Google Search Central. Guidance on redirect types and search interpretation. Accessed 30 September 2026.
- Site Moves With URL Changes — Google Search Central. Migration mapping, testing and monitoring guidance. Accessed 30 September 2026.
- How HTTP Status Codes Affect Google Crawlers — Google Crawling Infrastructure. Response interpretation; successful delivery alone does not establish indexing. Accessed 30 September 2026.
Put the Review Into Practice
Use the LLMIC documentation to choose the supported workflow in your installed build. Keep the source evidence with the action and verify the published result. Compare LLMIC plans when you are ready to organise this work in the Mac app. A completed technical check does not guarantee indexing, rankings or traffic.
Continue with Website Redirect Checklist for the next part of this workflow.
Check the website behind the idea.
Use LLMIC to crawl pages, review the evidence and organise the next actions in one native Mac workspace.